Head to head · verified Sep 5, 2026
L40S vs A100: inference board or training veteran
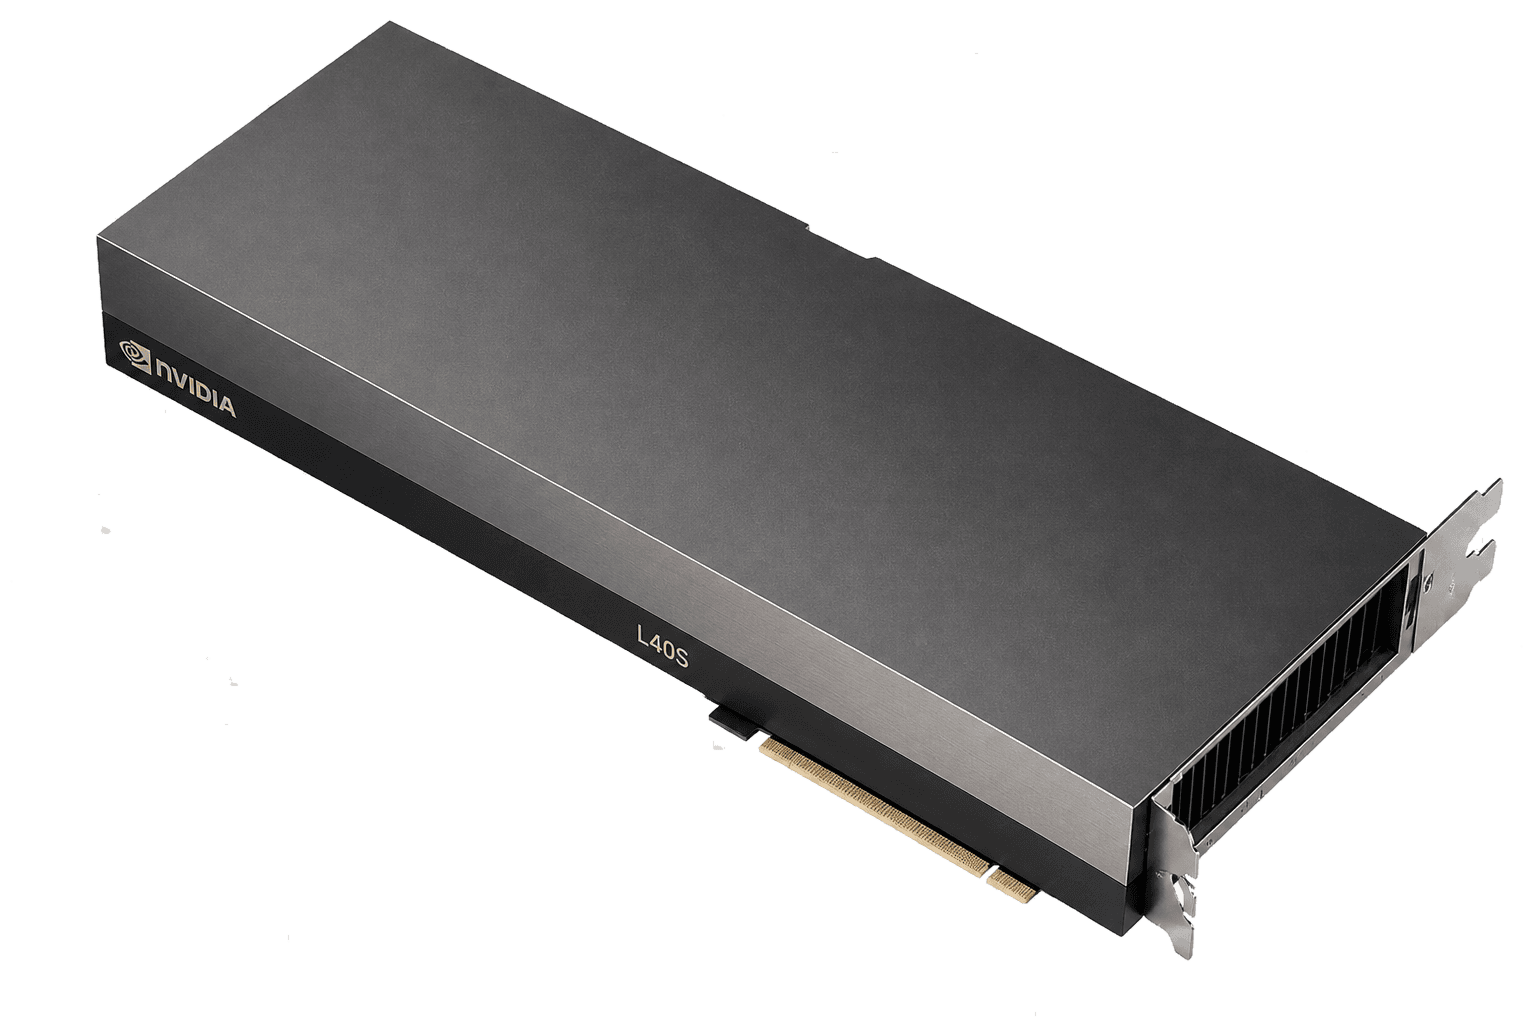
L40S is the Ada inference and graphics board with FP8. A100 is the Ampere training veteran with 80 GB of HBM2e and NVLink. I rent L40S when 48 GB holds and the job is inference. I rent A100 when the model needs the capacity, bandwidth or fabric.
L40S$0.79
VRAM48 / 80 GB
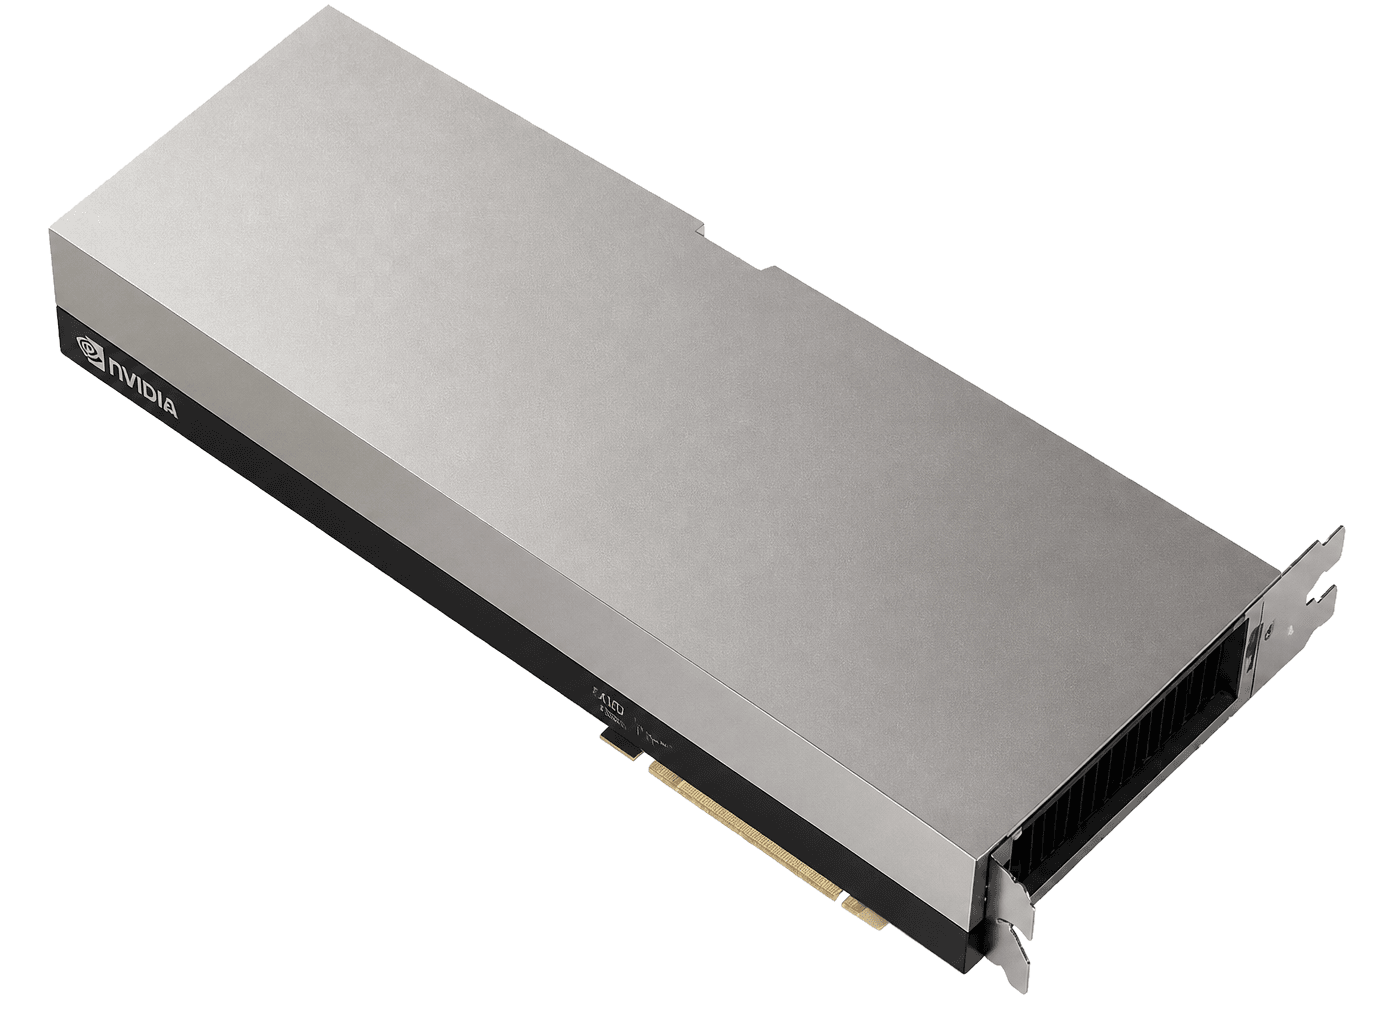
A100$1.19
The resultSplit: workload first
The result
Split: workload first
Pick: it depends
Inference that fits 48 GB: L40S. Training, 80 GB models or NVLink: A100. Both are older than the Hopper conversation, and both can still be the right hour.
In brief
What to know before you pick
- L40S: 48 GB GDDR6, ~864 GB/s, FP8, no NVLink. A100: 80 GB HBM2e, ~2 TB/s, NVLink, no FP8.
- L40S wins on price and Ada features for inference. A100 wins on capacity and training.
- Check the A100 variant. PCIe and SXM are different hours.
Same fields
The comparison
Catalog facts first. The pick above is editorial. Confirm the live on-demand row before you provision.
| Field | L40S | A100 |
|---|---|---|
| VRAM | 48 GB | 80 GBWins this row |
| Memory | GDDR6Tie | HBM2eTie |
| Bandwidth | 864 GB/s | 2,039 GB/sWins this row |
| Catalog from-price | $0.79Wins this row | $1.19 |
| Cheapest indexed on | RunPod | Vast.ai |
| On-demand rows in sample | 5 | 7 |
| In-stock rows | 4 | 4 |
| Architecture | ada | ampere |
Rent L40S if
Quantized and FP8 inference under 48 GB, image and video generation, rendering and encode, teams that want the lowest hourly rate on a datacenter board.
Skip it if NVLink training, jobs that need HBM bandwidth, anyone who actually needed 80 GB.
Rent A100 if
80 GB of capacity, HBM bandwidth, NVLink for multi-GPU training, FP64 work, and MIG-style partitioning of a big card.
Skip it if Greenfield FP8 training, people who needed H200 memory, anyone offered a 40 GB A100 as if it were 80.
L40S
- 48 GB ECC without Hopper rent
- Strong FP32/graphics path vs A100
- Datacenter board, not a gaming cooler lottery
A100
- 80 GB with NVLink and MIG, a real datacenter product, not a GeForce
- Deep catalog, mature images, fewer Blackwell surprises
- Often the cheapest *serious* 80 GB hour
Start from the workload
L40S is built for inference, graphics and video. FP8 on Ada gives it a modern inference path that A100 never had. If the model fits 48 GB, you are often paying A100 prices for capacity you do not use.
A100 is a training and capacity card. 80 GB and HBM2e are the point. If your model or batch needs them, L40S is a false economy.
GDDR6 vs HBM2e
A100 moves roughly 2 TB/s. L40S moves about 864 GB/s. Memory-bound decode runs faster on A100 at the same batch. FP8 and Ada kernels can claw some of that back for supported models.
Benchmark your own stack before you assume one beats the other.
NVLink and MIG
A100 supports NVLink and MIG partitioning. L40S has neither NVLink nor MIG in the datacenter sense. If you split one big card across tenants, or train across GPUs, that decides.
For single-GPU inference replicas, ignore the fabric and compare the hour.
The trap
How this comparison usually goes wrong
Treating GDDR6 and HBM2e as the same class. Expecting FP8 on A100. Comparing a PCIe A100 to an NVLink A100 node.
What I would do
The move
Name the bytes and the fabric. If 48 GB holds and no NVLink is needed, L40S. If 80 GB or multi-GPU training is the job, A100. Then check on-demand stock on the listing.
Catalog listings
L40S and A100 in this catalog
On-demand hours first. Spot and waitlists are labeled. From-prices are catalog samples, not a reservation.
ProvidersRegionBilling typeInterconnect/GPU/hrOpen provider

ProvidersRegionBilling typeInterconnect/GPU/hrOpen provider

Full review
The two reviews
Same product, full page. Specs, listings, who it is for. Confirm the live hour there.
Full review
NVIDIA L40S
Ada inference board: 48 GB GDDR6 ECC, 864 GB/s, no NVLink. The grown-up 4090 for people who need ECC and a datacenter slot. Not a trainer with a fabric.
Read the L40S reviewFull review
NVIDIA A100
Ampere’s 80 GB workhorse. Slower than Hopper, cheaper than denial. Still the right hour when the software is stuck on A100 images or the H100 premium is a tax you will not earn back.
Read the A100 reviewFAQ
L40S vs A100 questions
Is L40S better than A100?+
For FP8 inference under 48 GB, often yes on price. For 80 GB models, training and NVLink, no. They are different tools.
L40S vs A100 for fine-tuning?+
LoRA that fits 48 GB can run on L40S. Full fine-tunes and larger models belong on A100 80 GB or Hopper.
Does L40S support FP8?+
Yes. Ada supports FP8. A100 does not. That matters for modern inference stacks.
Which is cheaper per hour?+
Compare the on-demand rows in the table above. L40S is usually the lower hour, but cheap is not the test if the model does not fit.
Keep comparing