Head to head · verified Sep 5, 2026
L40S vs H100: do not rent Hopper for a 48 GB job
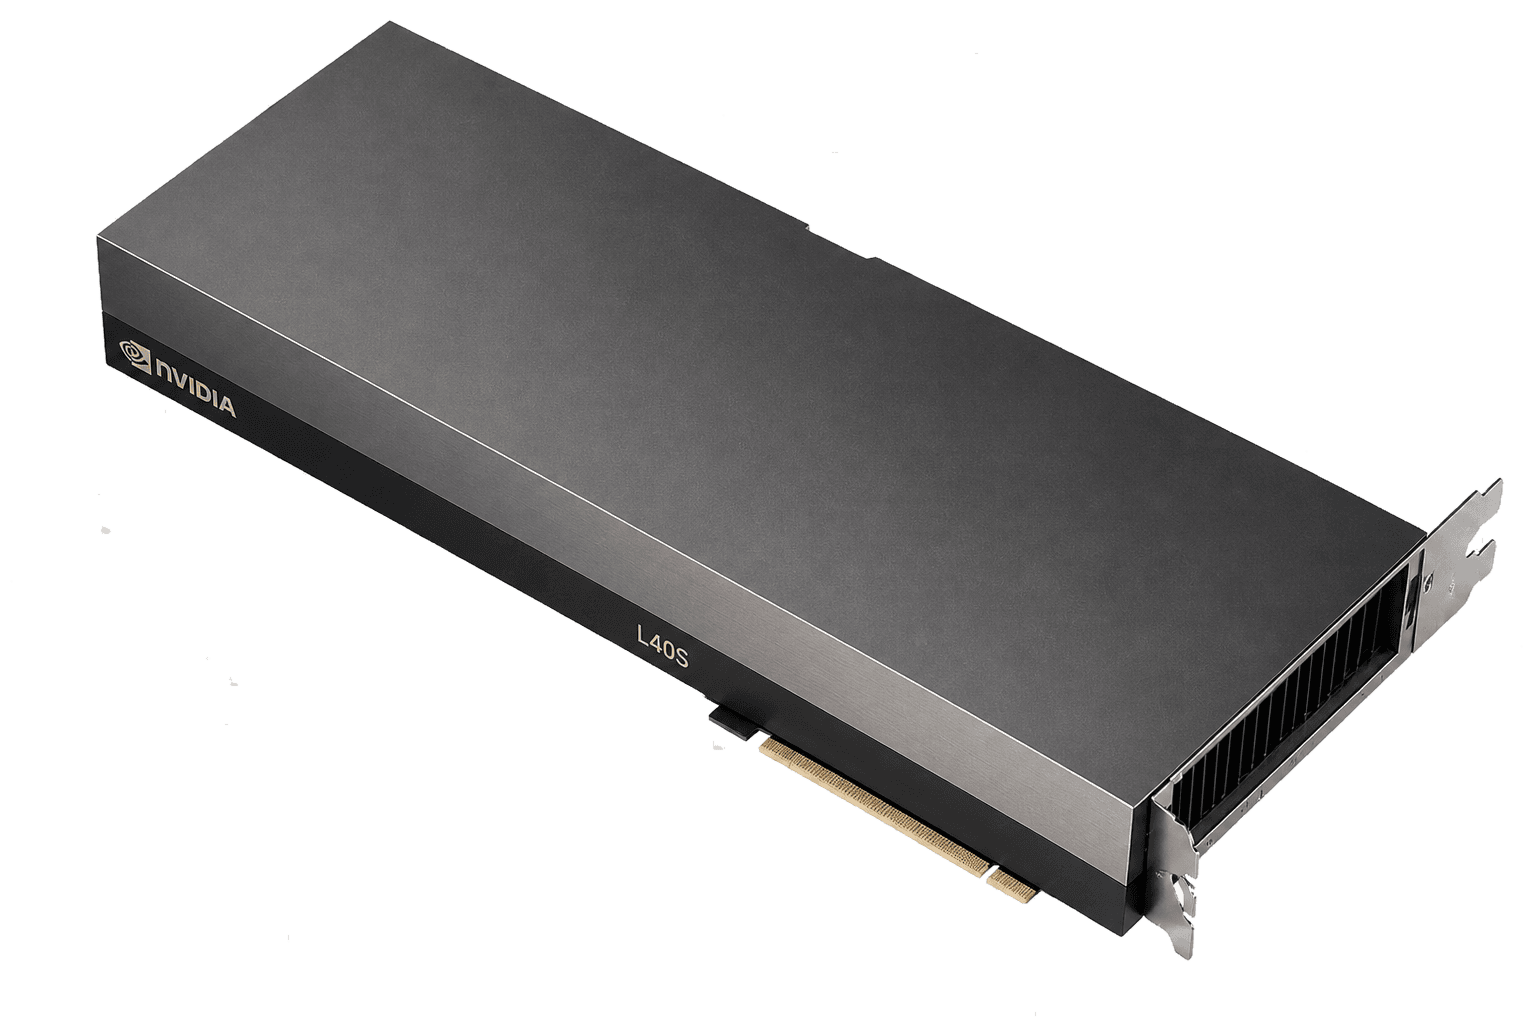
L40S is the inference board with FP8 and a small bill. H100 is the HBM and NVLink hour. I rent L40S when 48 GB holds and I do not need a fabric. I rent H100 when memory bandwidth, capacity or multi-GPU scaling is the job.
L40S$0.79
VRAM48 / 80 GB
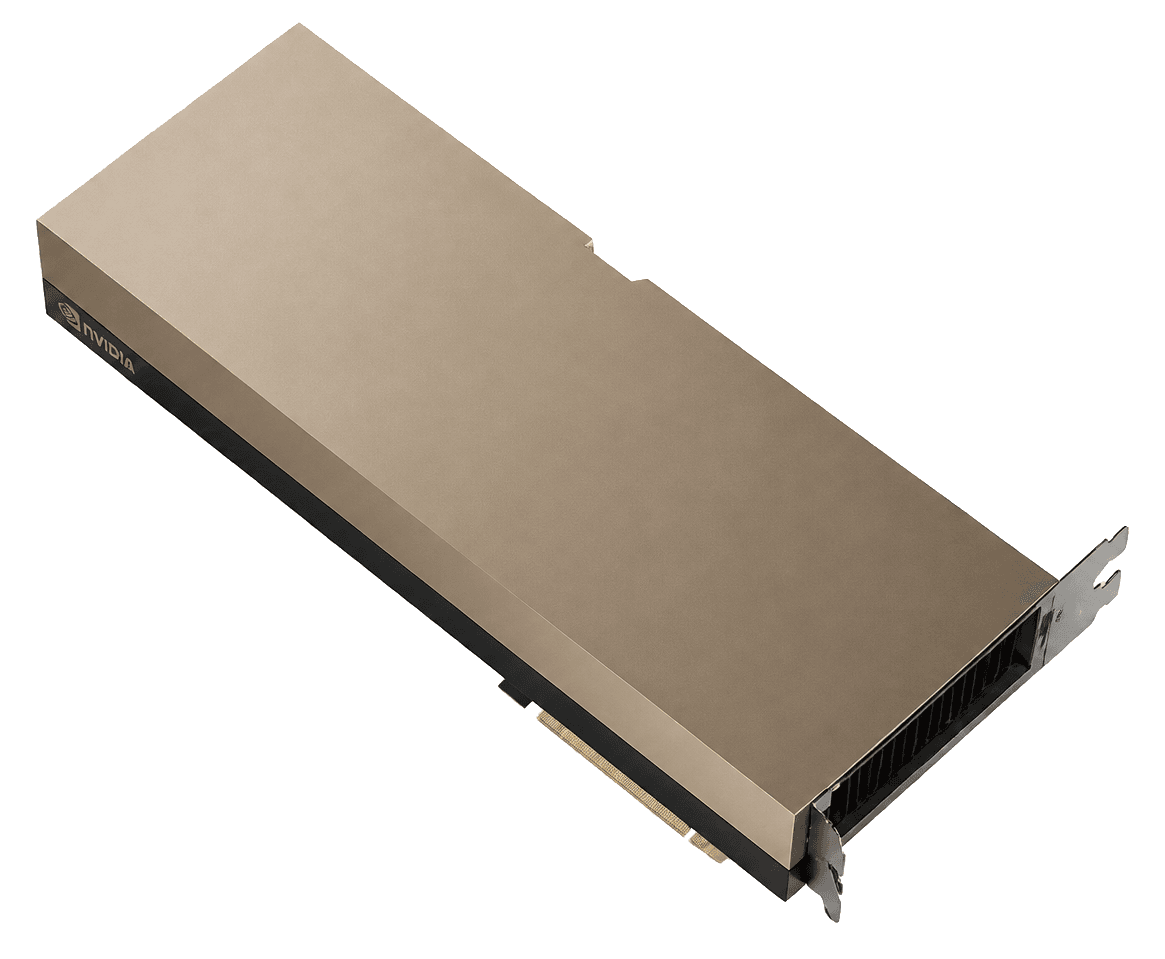
H100$1.73
The resultSplit: inference vs training
The result
Split: inference vs training
Pick: it depends
If the model and KV cache fit 48 GB and you serve single-GPU replicas, rent L40S and keep the delta. If you train, need 80 GB or NVLink, rent H100.
In brief
What to know before you pick
- L40S: 48 GB GDDR6, ~864 GB/s, FP8, no NVLink. H100: 80 GB HBM3, ~3.35 TB/s, NVLink on SXM.
- Inference under 48 GB favors L40S. Training and bandwidth-bound serving favor H100.
- The cheapest hour is only cheaper if the job fits.
Same fields
The comparison
Catalog facts first. The pick above is editorial. Confirm the live on-demand row before you provision.
| Field | L40S | H100 |
|---|---|---|
| VRAM | 48 GB | 80 GBWins this row |
| Memory | GDDR6Tie | HBM3Tie |
| Bandwidth | 864 GB/s | 3,350 GB/sWins this row |
| Catalog from-price | $0.79Wins this row | $1.73 |
| Cheapest indexed on | RunPod | Vast.ai |
| On-demand rows in sample | 5 | 15 |
| In-stock rows | 4 | 10 |
| Architecture | ada | hopper |
Rent L40S if
Quantized LLM inference, diffusion and video, rendering, batch jobs under 48 GB, teams optimizing cost per token on a datacenter board.
Skip it if NVLink training, jobs that need HBM bandwidth, anyone who actually needed 80 GB.
Rent H100 if
Training with NVLink, 70B-class serving with a large KV cache, bandwidth-bound decode, and anything that depends on Hopper’s Transformer Engine.
Skip it if Context windows that blow the KV cache, multi-node jobs that need a reserved fabric, or anyone shopping a 4090 workload with Hopper money.
L40S
- 48 GB ECC without Hopper rent
- Strong FP32/graphics path vs A100
- Datacenter board, not a gaming cooler lottery
H100
- The SKU every catalog actually stocks. You can compare an hour, not a waitlist
- FP8 Transformer Engine is the reason this generation still trains at a sane $/step
- MIG exists when you want to split an 80 GB card instead of overpaying for a second one
Does the job fit 48 GB?
The most expensive mistake is renting H100 for a 24 to 40 GB inference job. L40S gives you ECC, FP8 and a modern Ada path at a fraction of the hour.
The second most expensive mistake is renting L40S and sharding a model that needed 80 GB. Count the bytes, not the badges.
Bandwidth is the gap
H100 SXM has roughly four times L40S memory bandwidth. Decode at small batch is bandwidth-bound, so H100 pays off when latency per token matters.
At larger batch and FP8 kernels the gap narrows. Measure your model.
NVLink and training
L40S has no NVLink. Multi-GPU training over PCIe is a tax. H100 SXM is the reference for multi-GPU training.
For independent inference replicas, you can ignore the fabric and compare cost per token.
The trap
How this comparison usually goes wrong
Using H100 for a job that fits L40S. Using L40S for multi-GPU training over PCIe. Comparing different billing types in one table.
What I would do
The move
Check the bytes first, then the fabric. If L40S holds, stop. If it does not, open H100 and confirm SXM vs PCIe, stock and on-demand billing.
Catalog listings
L40S and H100 in this catalog
On-demand hours first. Spot and waitlists are labeled. From-prices are catalog samples, not a reservation.
ProvidersRegionBilling typeInterconnect/GPU/hrOpen provider

ProvidersRegionBilling typeInterconnect/GPU/hrOpen provider




Full review
The two reviews
Same product, full page. Specs, listings, who it is for. Confirm the live hour there.
Full review
NVIDIA L40S
Ada inference board: 48 GB GDDR6 ECC, 864 GB/s, no NVLink. The grown-up 4090 for people who need ECC and a datacenter slot. Not a trainer with a fabric.
Read the L40S reviewFull review
NVIDIA H100
The default datacenter hour. 80 GB of HBM3 is enough for most 70B work if you manage the KV cache. It is not a bargain because the FLOPs slide is pretty. It is a bargain when the job already fits.
Read the H100 reviewFAQ
L40S vs H100 questions
Is L40S a cheaper H100?+
No. It is a different product class: less memory, far less bandwidth, no NVLink, and a much lower hour. It replaces H100 only for jobs that fit.
L40S vs H100 for LLM inference?+
L40S for quantized models under 48 GB. H100 for larger models, larger KV cache and bandwidth-bound serving.
Can L40S train models?+
Small fine-tunes and LoRA, yes. Multi-GPU pretraining belongs on NVLink-class hardware.
Which has better price per token?+
It depends on your model and batch. L40S often wins when the model fits. Benchmark before you commit.
Keep comparing